Benchmarks for AI Models and Agents on CAD Tasks
Parametric CAD Bench evaluates models and AI agents on parametric CAD tasks.
V3 is the latest version and contains 100 complex FreeCAD tasks: 30 creation tasks from text, 30 create-and-edit tasks from text, and 40 creation tasks from engineering drawings.
V1 and V2 remain available as historical leaderboards.
 gnucleus.ai
 Hugging Face
Parametric CAD Bench V3 Leaderboard
View full leaderboard →| Rank | Model | Agent | Create | Create + Edit | Image-to-CAD | Overall | Cost (USD) |
|---|---|---|---|---|---|---|---|
1 | Claude Opus 5.5(max) | Claude Code | 50.87 | 39.69 | 84.66 | 61.03 | $573.94 |
2 | Claude Opus 5.5(max) | mini-swe-agent | 42.79 | 41.38 | 81.77 | 57.96 | $498.28 |
3 | GPT-6 Astra(max) | Codex | 52.26 | 44.37 | 69.70 | 56.87 | $317.81 |
4 | Claude Fable 5.1(max) | Claude Code | 55.48 | 36.75 | 72.71 | 56.75 | $1,056.04 |
5 | Claude Opus 5(max) | Claude Code | 49.48 | 36.52 | 62.64 | 50.86 | $1,012.21 |
6 | Gemini 3.8 Flash(high) | mini-swe-agent | 47.94 | 31.22 | 31.10 | 36.19 | $271.85 |
7 | Grok 4.7(high) | Grok Build | 45.57 | 34.63 | 26.91 | 34.82 | $670.22 |
8 | GPT-5.6 Sol(max) | Codex | 36.23 | 24.78 | 29.20 | 29.98 | $291.99 |
9 | Grok 4.6(high) | Grok Build | 41.61 | 33.45 | 13.00 | 27.72 | $390.94 |
10 | Gemini 3.8 Flash(high) | Antigravity | 43.28 | 25.32 | 17.45 | 27.56 | $196.74 |
11 | Kimi K3(max) | mini-swe-agent | 39.11 | 23.49 | 15.36 | 24.92 | $314.55 |
12 | Muse Spark 1.3(max) | mini-swe-agent | 33.61 | 24.33 | 8.84 | 20.92 | $357.03 |
13 | GPT-5.6 Terra(max) | Codex | 23.32 | 23.23 | 8.18 | 17.24 | $215.12 |
Scores are on a 0–100 scale. Overall is the mean reward across all 100 tasks; failures count as zero.
Benchmarks Tasks
Run Benchmark →3D Parametric Part Generation
Generate editable, parametric 3D CAD part models from natural-language prompts and reference inputs.
Assembly Generation
Generate multi-part assemblies with proper mates, constraints, and component hierarchy.
Complex CAD workflow
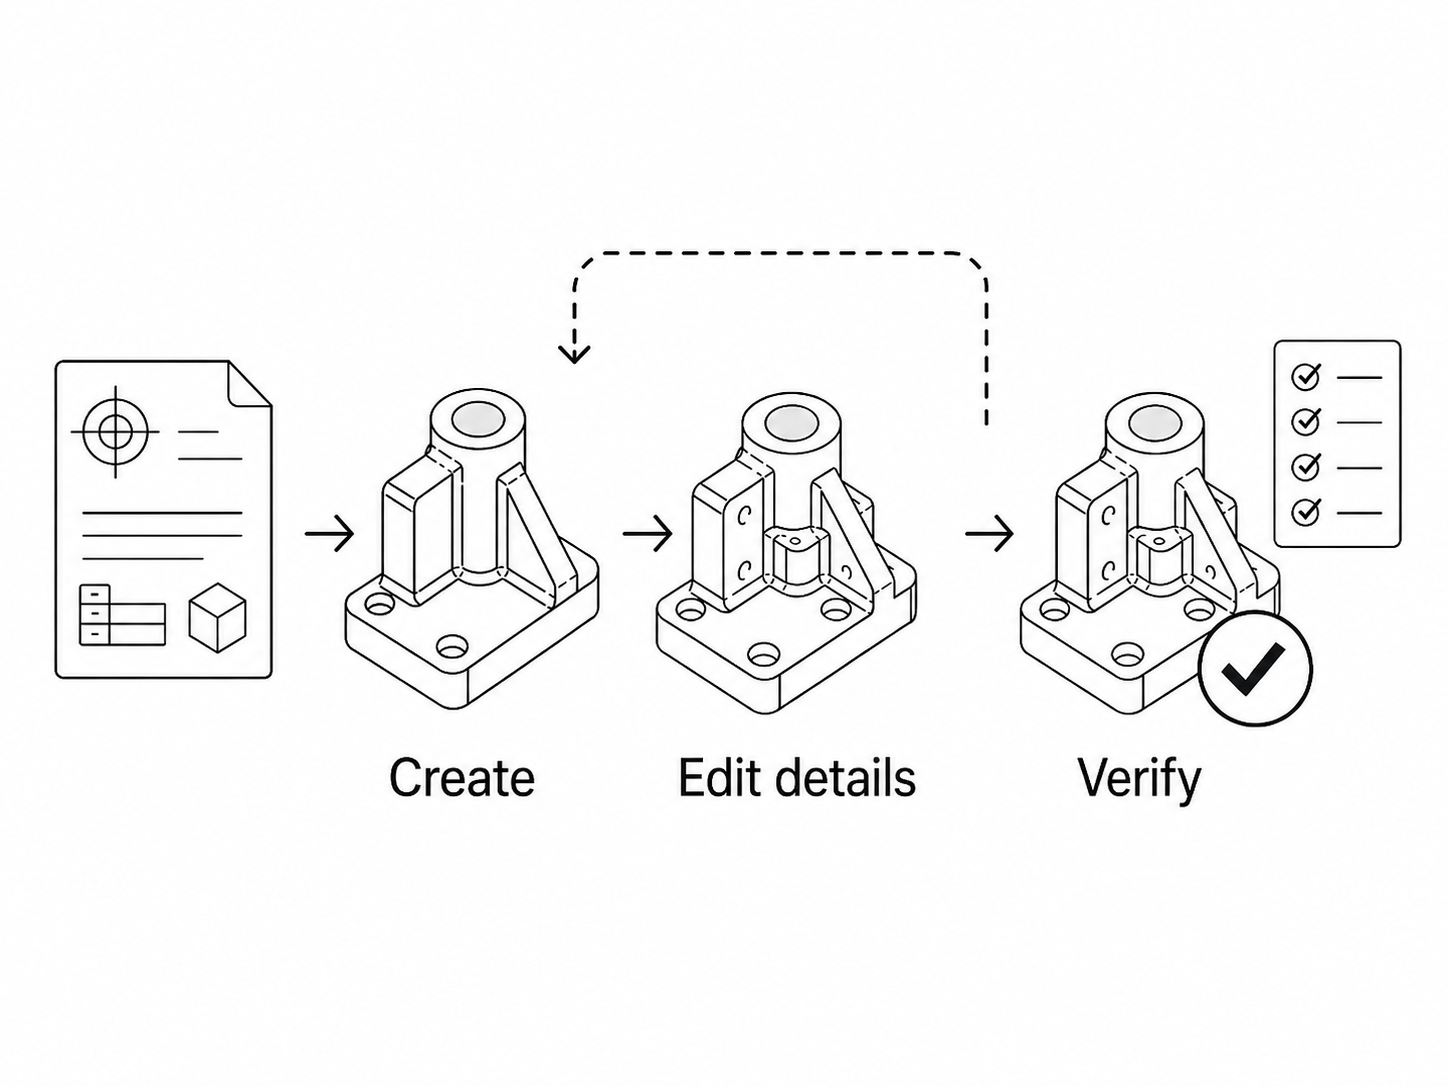
Multi-step CAD workflows that generate, iteratively edit, and verify designs until the model meets the target spec.
Evaluation Methods
View Evaluator →CAD evaluation should check not only visual similarity, but also whether the generated CAD is valid, accurate, rebuildable, and consistent with the design spec.
Each task is scored automatically in a sandboxed CAD environment, comparing the generated CAD against the design spec and reference CAD (ground truth) across the axes below. Scoring is deterministic — same output, same score.

Geometry Accuracy
Uses an oriented-bounding-box size gate and revised geometry weights to compare against the reference.

Component & Spatial Alignment
Uses stricter per-component comparisons and stronger spatial alignment scoring.

Parametric Correctness
Verifies CAD model consistency with the spec parameters.

Topology / Structure
Evaluates topological validity and part structure correctness.

Agent Workflow Success
Assesses task completion rate and workflow correctness.

Efficiency
Measures token usage, execution time, and resource efficiency.
Latest Updates
September 24, 2026
Two Claude Opus 5.5 results join the V3 leaderboard. Claude Code reaches 61.03% and mini-swe-agent with the multimodal bridge reaches 57.96%, with both systems setting new image-to-CAD highs.
September 21, 2026
A new 100-task cohort spans 30 creation tasks, 30 create-and-edit tasks, and 40 engineering drawings. V3 introduces a stricter scorer and stronger runtime isolation. The release report covers 11 public runs, cost efficiency, and the design and limitations of the mini-swe-agent multimodal bridge.
September 8, 2026
The V2 release upgraded the 100-task benchmark to FreeCAD 1.1, isolated held-out grader assets, fixed reward reporting, and added 10 frontier-model runs. Its original results remain available as a historical leaderboard.
August 14, 2026
Five new (agent, model) cells join the board, taking the top five spots; the leaderboard now holds 15 entries. Claude Opus 5 via Claude Code leads at 0.906 — the first result above 0.9 — closing 44% of the remaining gap to a perfect score while costing less than the previous leader. Grok 4.6 offers the best balance of cost and performance, delivering 97.6% of the top score at 67.6% of the cost. In the 91 days since the May run the engineering slice moved sharply — the weakest new cell would have ranked first in May, and the gain went almost entirely into geometry rather than spec.
May 13, 2026
A new benchmark for AI agents that design parametric 3D mechanical parts in FreeCAD. Multi-step agentic loop scoring geometric correctness and consistency between the generated CAD and the provided spec, across 10 agent–model combinations spanning frontier vendors. Early results: GPT-5.5 via Codex leads at 0.832 with a visible harness effect — and is also the most expensive combination at $170.
May 10, 2026
A programmatic grader for evaluating AI-generated parametric FreeCAD parts — checks geometry similarity to the ground truth and CAD/spec consistency.
May 08, 2026
Open-sourced cad-gen-freecad on HuggingFace — native FreeCAD parts with parametric feature history, design specs, and renderings, aimed at accurate, parametric CAD generation from text prompt.